| ▲ | numpad0 4 hours ago | |
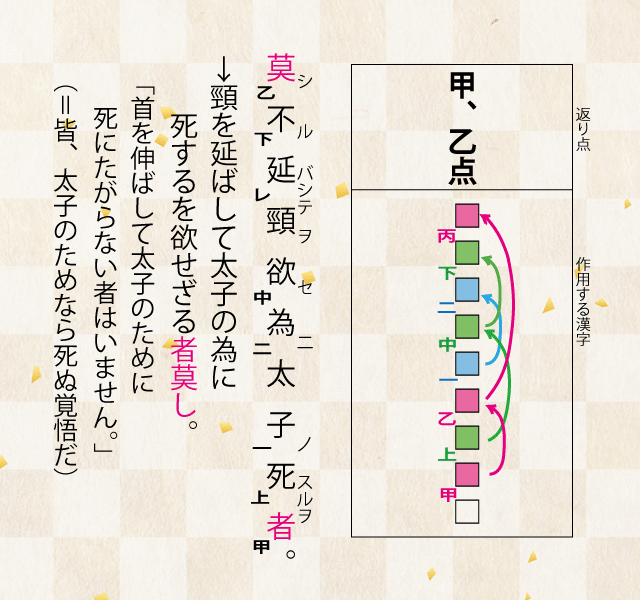
Maybe this is less dependent on rendering engine or easier to use. Or maybe because it could be done and was done. From practicality standpoint, this would not work on unprepared texts, as pronunciation of Japanese words are a bit arbitrary and so correct pronunciations would need to be manually selected for each words. i.e. "maize" could be read "corn". I believe LLMs don't necessarily have good intuition for that, being trained on plain texts. As to how could such a situation could ever manifest: I would blame the fact that the official language of historical Japanese governments having been a really creative interpretation of medieval Chinese[1] sprinkled with labels and jumps and supplements[2][3], resulting in people just accepting wild divergence between literal and spoken Japanese. I'm not a linguist or a language major so I'd happy if anyone could further elaborate... 1: https://en.wikipedia.org/wiki/Kanbun 2: https://youtu.be/_k0I6bi2pYs?t=248 3: https://d1ysbfo9sxjda0.cloudfront.net/wp-content/uploads/201... | ||